Google Open-Sources Harness2, a Recursive Agent Harnessing Framework
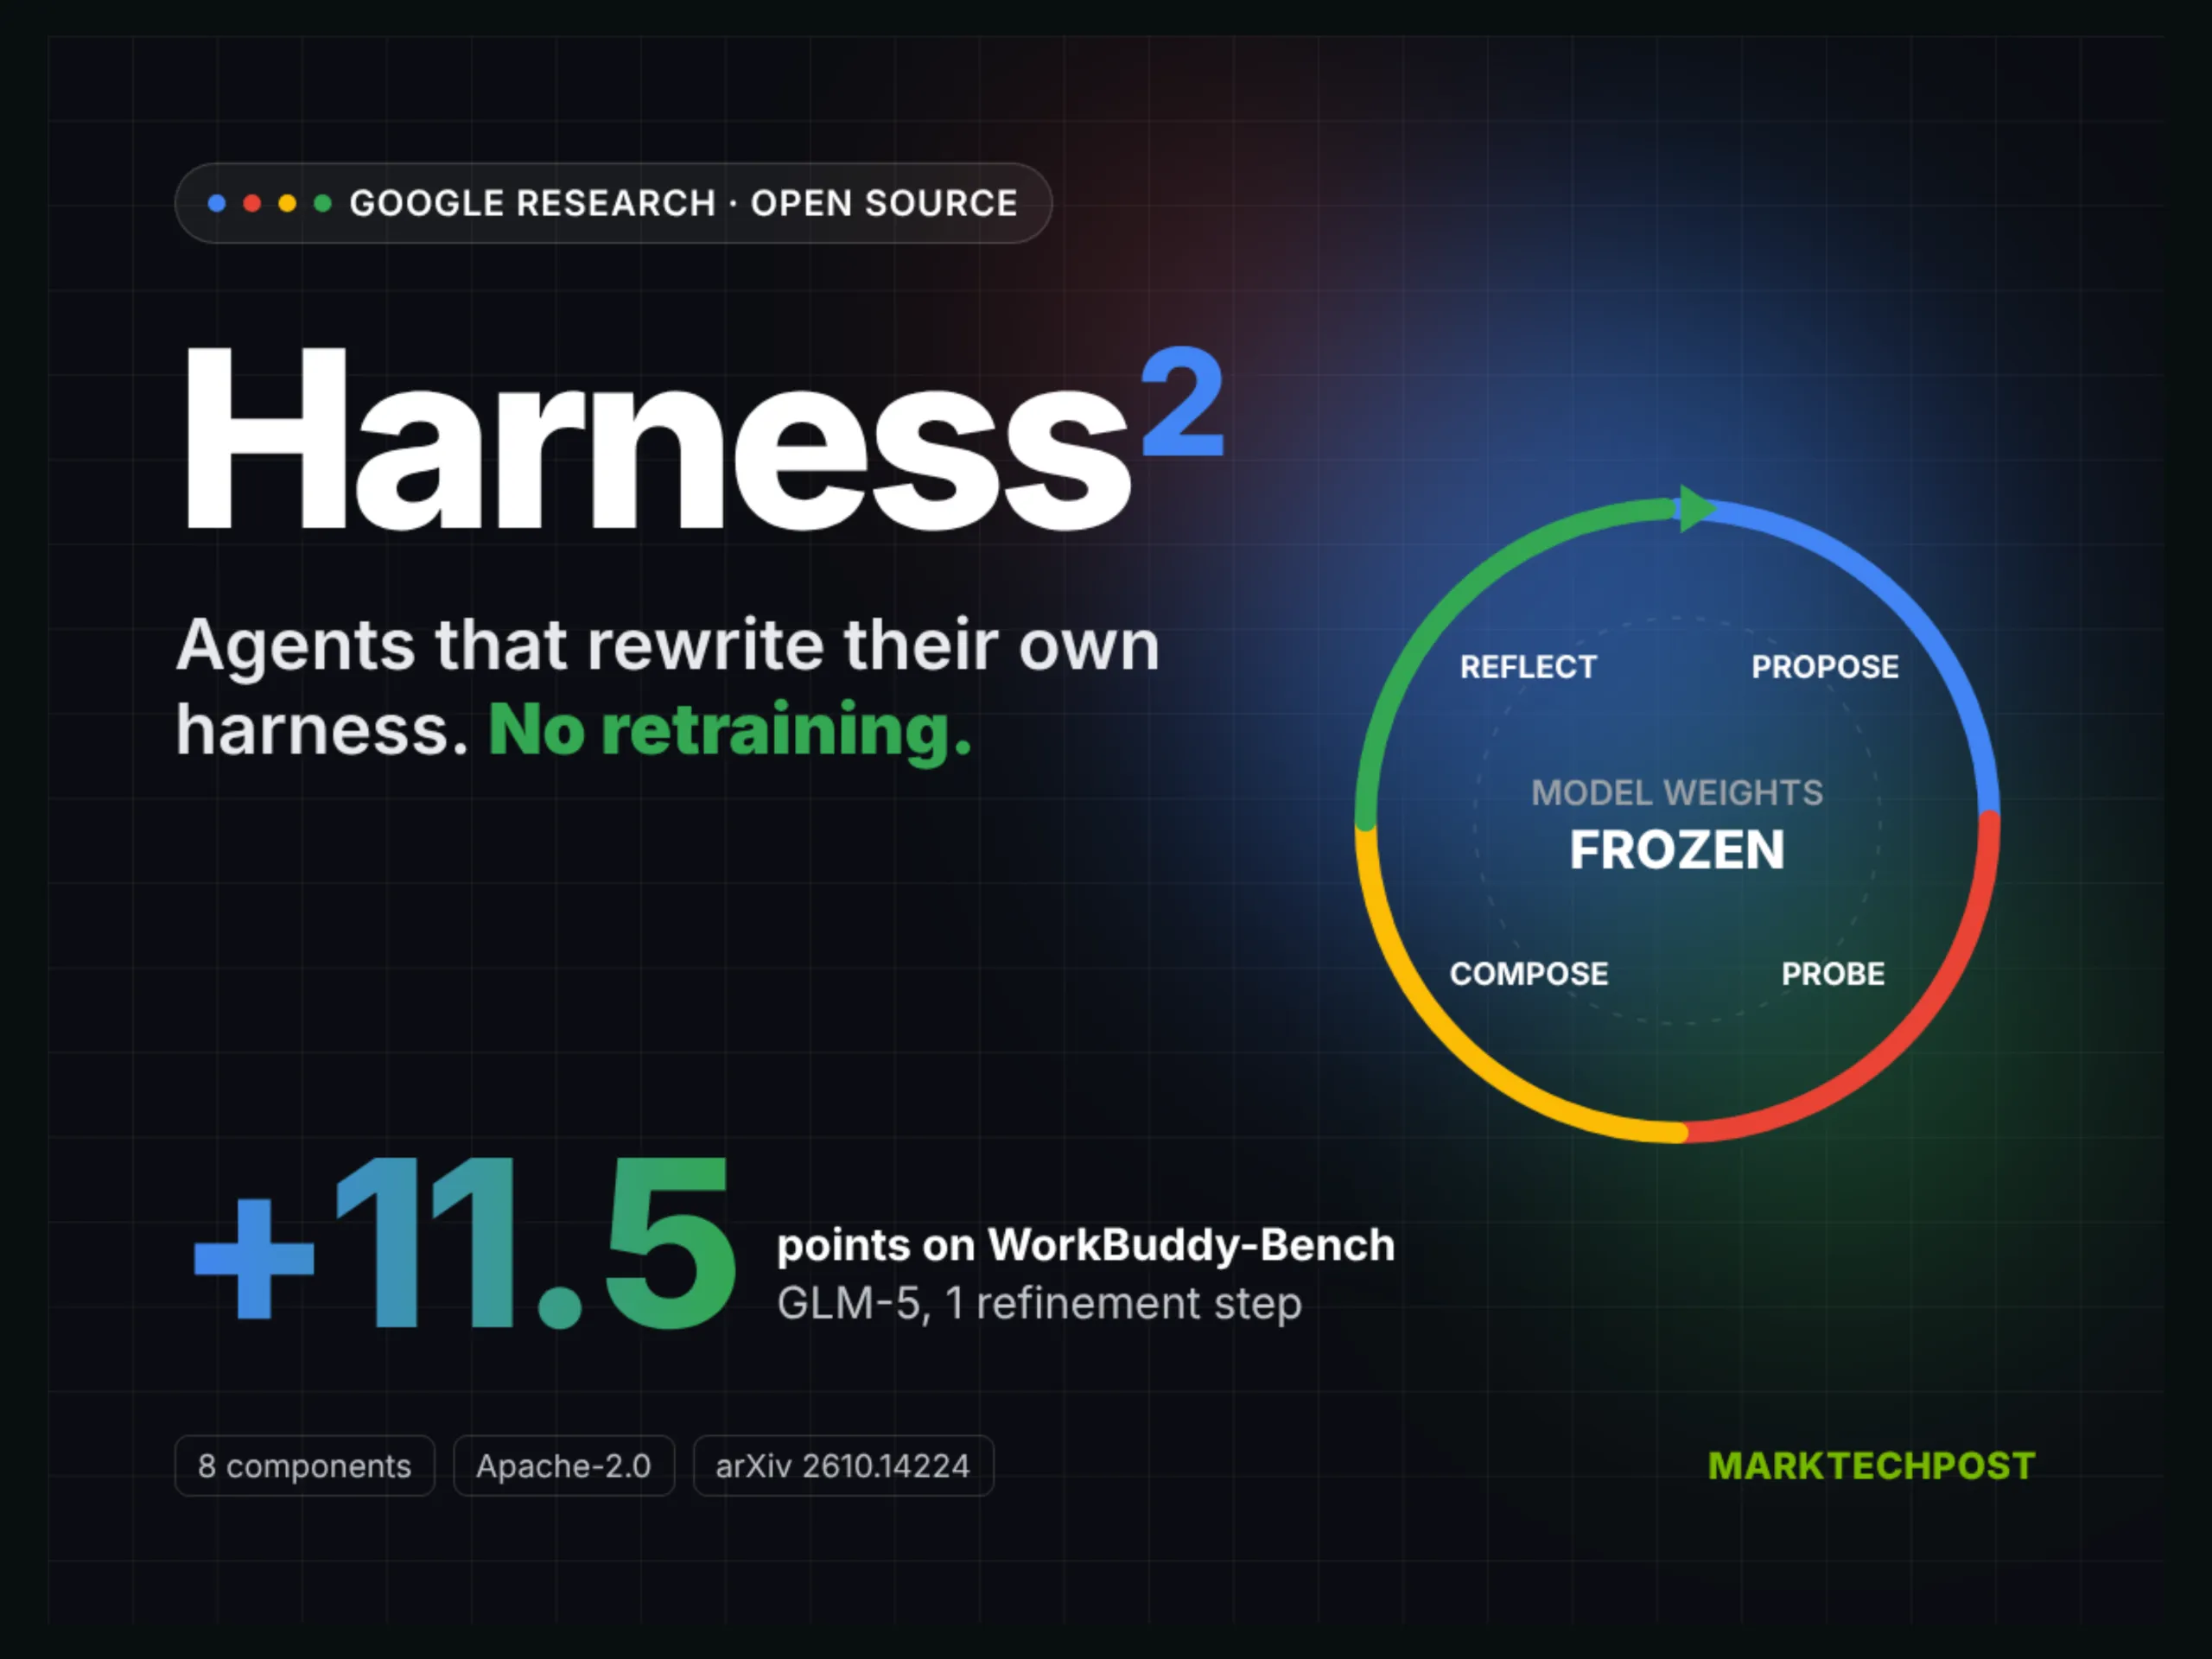


Google Cloud AI Research has open-sourced Harness². It is a recursive agent harnessing framework that improves the code and files around a frozen model. For developers, the pitch is simple. Your agent may get better without a better model.
TL;DR
- Size: A framework, not a model. 0 parameters trained; 8 editable harness components. Version 0.1.0.
- Runs on: Linux with Python 3.12 or 3.13 and uv. Model runs call models through Vertex AI. GPU requirement: Not disclosed.
- Performance: 1 refinement step improved all 4 model and harness setups on all 3 benchmarks.
- Best: GLM-5 under OpenCode rose from 64.2 to 75.7 on WorkBuddy-Bench (+11.5 points).
- Worst: GLM-5 under Codex gained only 1.2 points on JobBench (23.6 to 24.8).
What is Harness²?
Harness² is a plug-and-play framework from Google Research that refines an agent’s harness during deployment. A harness is everything around the model: prompts, tools, memory, skills and orchestration. Harnessing is the process of optimizing that system. Model weights never change.
The target setting is the open world. Tasks arrive unseen, and no verifier says whether an answer is right. The research team argues that most self-improvement methods assume labels or test cases. Harness² is built to work without them.
What are the 8 harness components?
Harness² exposes 8 editable components, each mounted as a file:
- System prompt
- Guardrails
- Memory
- Tool guidance
- Subagents
- Skills
- Scripts
- Plugins (middleware)
They cover context construction, the tool interface, delegation and behavior inside the tool loop. The layout extends the 7-file split from earlier Agentic Harness Engineering work by 1 component.
How does recursive agent harnessing work?
The framework runs two linked levels of recursion:
- Task-level recursion uses a contrastive Propose, Probe, Compose step. First, the agent runs the task once with the base harness. An editor then proposes 2 candidates. The invariant candidate targets general agent failures such as planning or tool use. The domain candidate targets knowledge and procedures for the current domain. Both candidates run on the same task. The composer compares their trajectories against the reference and keeps only edits backed by observed behavior.
- Harnessing-level recursion happens after each task. A reflector stores the adopted harness plus an EXPERIENCE.md file of lessons. This library guides future proposals. Each new task still starts from the base harness.
The budget k scales the search. Parallel mode probes k invariant and k domain candidates, then makes k compositions. Sequential mode chains k refinement steps.
How does Harness² perform on benchmarks?
The research team tested 3 professional benchmarks: WorkBuddy-Bench, JobBench and Harvey’s LAB. Executors were Gemini 3.5 Flash and GLM-5 under OpenCode and Codex. The default editor was Claude Opus 4.8. Results are means over 3 runs.
Source: Harness² paper, Tables 1 and 2.
Weaker executors gained more. After 1 step, GLM-5 beat base Gemini 3.5 Flash on WorkBuddy-Bench. Parallel recursion at k=5 lifted Gemini under OpenCode to 80.8 on WorkBuddy. On WorkBuddy-Bench, 3 of 4 setups also used fewer steps per task. Gemini under OpenCode fell from 25.4 to 21.9.
How does it compare with other harness methods?
*Scores as measured in the Harness² paper; the other methods did not report these benchmarks themselves.
How do you install and run Harness²?
The README targets Linux, Python 3.12 and uv. A local demo runs both recursion modes without model credentials:
source .venv/bin/activate
uv pip install -e ‘.[render]’
harness2-demo –output runs/demo –k 2
Model-backed runs need Node.js 20+, the Google Cloud CLI and a Vertex AI project. LAB needs Pandoc and Poppler. WorkBuddy-Bench needs Docker. Executors are OpenCode by default, or Codex with –substrate cx.
Key Takeaways
- Harness² rewrites an agent’s harness at test time; weights stay frozen.
- 1 step lifted GLM-5 by 11.5 points on WorkBuddy-Bench.
- Propose, Probe, Compose replaces ground-truth labels with behavioral contrasts.
- A lessons library carries improvements to future tasks.
- Expect extra runs per task, and sandbox it yourself.
Check out the Paper, GitHub Repo, Paper and Project Page. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.